What Is Self-Service Cloud?
A cloud portal can look self-service without the underlying service actually operating that way.
A customer may click “Request” for a GPU server, yet an operations team may still need to read the ticket, check inventory manually, configure networking, create credentials and email the customer when the environment is ready.
That is a valid operating model, but it is not the same as end-to-end cloud self-service.
The more useful question is:
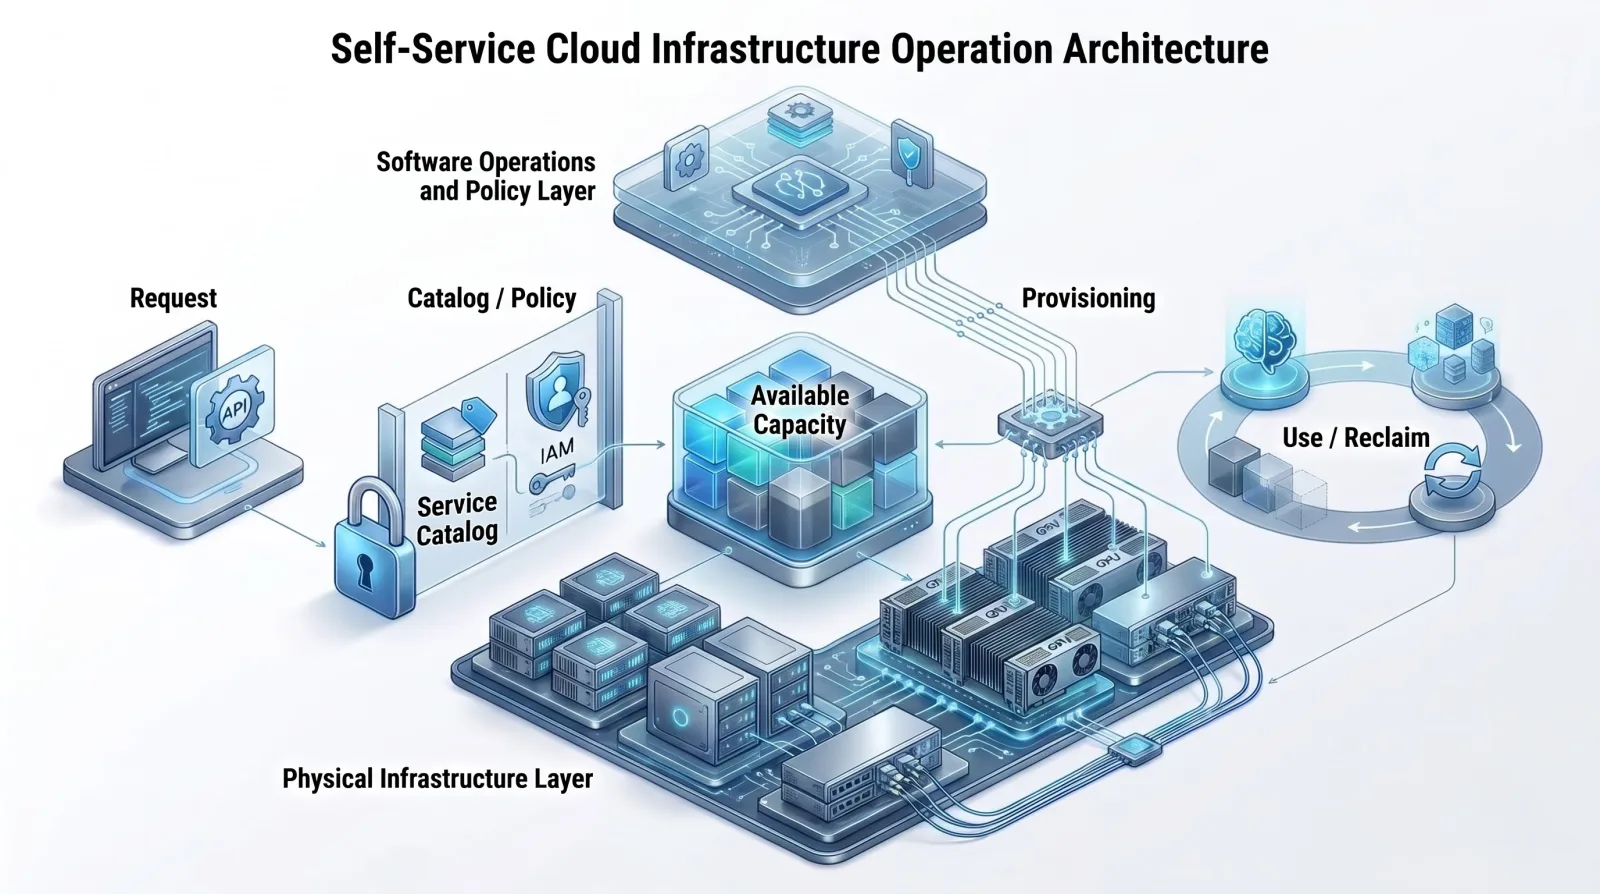
Does a customer request flow through policy, available capacity, provisioning, service state, usage and resource recovery without requiring a provider employee to manually rebuild the workflow each time?
NIST identifies on-demand self-service as one of the essential characteristics of cloud computing: a consumer can provision computing capabilities as needed without requiring human interaction with each service provider.
For GPU cloud operators, that definition matters because self-service is not a user-interface feature. It is an operating model.
Self-Service Is More Than a Portal
Suppose a customer requests one eight-GPU server for seven days.
The service may need to:
- validate the customer and entitlement
- check organization policy and quota
- verify available capacity
- reserve the resource
- provision compute, network and storage
- create credentials and access
- expose the correct service state
- record usage
- terminate the service
- clean and return capacity
A portal is only the entry point to that sequence.
The Core Building Blocks
Service catalog
Customers need a defined set of services they can actually order.
Identity and organization
The platform must know who the customer is, which organization they belong to, and what they are allowed to request.
Policy and quota
Self-service does not mean unlimited consumption. Quotas, eligibility and service policies can constrain requests.
Available capacity
A catalog item may exist even when the required GPU shape is not currently available.
Provisioning
The request has to become a usable compute environment. That can include servers, networking, storage, images, runtime and credentials.
Service state
Customers need a reliable view of whether the service is requested, provisioning, active, terminating, failed or retrying.
Metering and billing context
Technical telemetry is not automatically billable usage. Allocation, reservation and contract context may also be required.
Termination and recovery
Resources must be cleaned, released and returned to an available pool when the service ends.
Portal-Only vs. End-to-End Self-Service
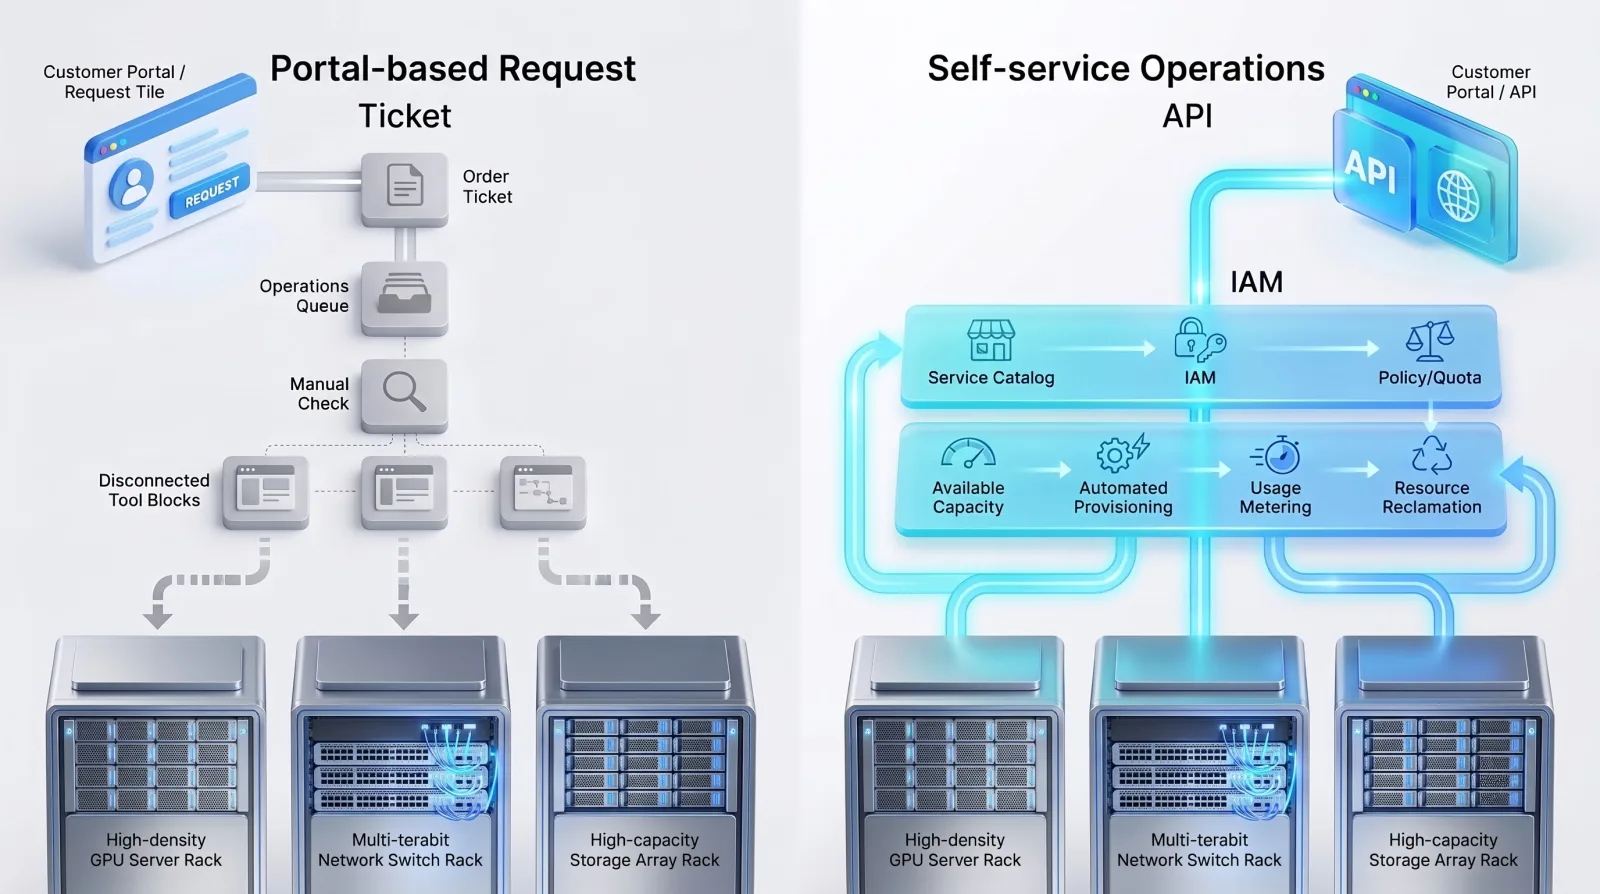
A portal-only environment may still rely on manual fulfillment behind the scenes.
An end-to-end self-service environment connects the request to policy, capacity, provisioning, state, usage and lifecycle.
The goal is not to eliminate people. It is to let systems handle repeatable normal flows while operators manage policies, exceptions, capacity and incidents.
Self-Service and On-Demand Are Related but Different
Self-service is primarily about how the customer requests and controls a service.
On-demand is primarily about whether capacity can be requested and released as needed.
They often appear together, but they are not identical.
A reserved service can still be ordered through self-service. An on-demand request may still be subject to approval, quota or capacity constraints.
Can Dedicated Bare Metal Be Self-Service?
Yes.
Self-service does not require virtualization or shared GPUs.
OpenStack Ironic, for example, provides API-driven bare-metal provisioning. A dedicated physical server can still be offered through a cloud-style workflow if reservation, provisioning, access, service state and recovery are connected.
Failure States Matter
Assume GPU reservation succeeds but network provisioning fails.
A real self-service workflow must determine:
- whether to retry
- whether to retain or release the GPU reservation
- whether to clean partially created resources
- what state the customer sees
- whether billing is prevented from starting
Self-service quality is therefore not only about how quickly the happy path completes. It is also about whether service state remains consistent when something fails.
Where Thaki NeoCloud OS Fits
Thaki Cloud’s canonical NeoCloud OS architecture is:
Customer Infrastructure → Thaki NeoCloud OS → Customer NeoCloud Service
Thaki NeoCloud OS is the cloud platform that enables organizations with GPU and AI infrastructure to build and operate their own branded self-service, on-demand NeoCloud services.
Depending on the deployment, it can connect areas such as service catalog, provisioning, tenancy, allocation and scheduling, usage metering, billing integration, observability and lifecycle processes.
Actual scope and integration must be confirmed for each environment.
Summary
Self-service cloud is not defined by a portal.
It is the operating model that connects:
Catalog → identity and policy → capacity → provisioning → usage → metering → termination and recovery
That is what turns infrastructure into a repeatable cloud consumption experience.
FAQ
Does self-service require a web portal?
No. APIs can also provide a self-service interface.
Does self-service mean every request is automatically approved?
No. Policy, quota, entitlement and capacity constraints can still apply.
Can dedicated GPU servers be self-service?
Yes. Physical servers can be provisioned through cloud-style APIs and workflows.
Is self-service the same as on-demand?
No. They are closely related but describe different aspects of the operating model.
Does self-service eliminate operations teams?
No. It shifts their role toward policy, exceptions, capacity, incidents and service quality.
Building a Self-Service GPU or AI Cloud?
If you are turning owned GPU or AI infrastructure into a customer-facing service, Thaki Cloud can review how catalog, policy, provisioning, metering and lifecycle should connect in the operating architecture.
Contact UsRelated articles
- What Is GPU Cloud? How It Works, Types, Use Cases, and GPUaaS ExplainedGPU cloud provides on-demand access to GPU computing resources without requiring users to own the hardware. Learn how GPU cloud works, common deployment types, GPUaaS terminology, use cases, benefits, and key considerations.
- What Is an AI Factory? How It Differs from an AI Data CenterAn AI factory is an integrated infrastructure and operating environment for developing, training, deploying, and running AI at scale. Learn how it differs from an AI data center, its core components, lifecycle, and relationship to GPU cloud.
- What Is GPUaaS? How GPU as a Service WorksGPU as a Service (GPUaaS) provides access to GPU compute without requiring organizations to buy and maintain the hardware. Learn how it works, how it relates to GPU cloud, delivery models, operational capabilities, and key buying considerations.
- What Is a Private AI Cloud?A private AI cloud combines private-cloud infrastructure dedicated to one organization with accelerated compute, AI platforms, data services, security, and governance. Learn how it differs from public AI cloud, on-prem AI, sovereign AI, and air-gapped AI.
- Why Owning GPU Servers Is Not the Same as Operating a GPU CloudGPU hardware alone does not create a GPU cloud. Learn how GPU hosting differs from cloud service operations and why self-service, provisioning, scheduling, metering, lifecycle management, and service delivery matter.
- What Is a Neocloud? AI-First Cloud Infrastructure ExplainedNeocloud is an industry term for specialized cloud infrastructure built around GPUs and AI workloads. Learn how neoclouds differ from general-purpose hyperscalers, how they relate to GPU cloud and GPUaaS, and how infrastructure owners can build their own services.
- The Next Step for an AI Factory Is Cloud ServiceBuilding an AI Factory is not the same as operating a customer-facing cloud service. Learn which operational layers—provisioning, tenancy, scheduling, metering, billing, SLA, and lifecycle automation—are required to turn AI infrastructure into a consumable service.
- What Does It Mean to Turn AI Infrastructure into a Cloud Business?Owning AI infrastructure is not the same as operating a cloud business. Learn how infrastructure becomes a product and then an on-demand cloud service through catalog, ordering, provisioning, metering, billing, SLA, and lifecycle operations.
- What Is Bare Metal GPU? Bare Metal vs Virtualized GPULearn what bare metal GPU means, how it differs from GPU VMs, vGPU and passthrough, and which trade-offs matter for performance, isolation, flexibility, utilization and provisioning.
- Private AI Cloud vs Public AI Cloud: What’s the Difference?Compare private and public AI cloud across exclusivity, control, scalability, managed services, operating responsibility and cost structure, and learn which model fits different AI workloads.
- What Is GPU Scheduling? How AI Clouds Allocate GPU ResourcesLearn how GPU scheduling allocates scarce GPU resources across AI workloads, including queues, priorities, quotas, GPU type, topology, multi-GPU jobs, fragmentation, and provisioning.
- What Operations Platform Does an AI Factory Need After Deployment?Learn which capabilities are needed to operate an AI Factory after deployment, including provisioning, GPU scheduling, access and policy, observability, capacity management, metering, and lifecycle automation.
- What Is On-Prem AI? Why Enterprises Run AI on Their Own InfrastructureLearn what on-prem AI means, how it differs from private AI cloud, and why enterprises may run AI locally for data, model, network, latency, governance, and operational control.
- What Is GPU Multi-Tenancy? How Multiple Tenants Share GPU InfrastructureLearn how GPU multi-tenancy isolates users, compute, GPUs, networking, storage, IAM, quotas, scheduling, and usage across multiple tenants, and where vGPU, MIG, and Kubernetes fit.
- What Is GPU Provisioning? From Request to a Ready-to-Use GPU EnvironmentLearn how GPU provisioning turns a request into a usable GPU environment by coordinating compute, networking, storage, images, runtimes, access, and lifecycle automation.
- How to Turn an AI Factory into a Multi-Customer Cloud ServiceLearn what changes when an AI Factory becomes a multi-customer cloud service, including catalog, tenancy, provisioning, scheduling, metering, billing, SLA, self-service, and lifecycle operations.
- GPU Cloud Commercialization Readiness: What Should Operators Check?Evaluate whether your GPU infrastructure is ready for customer-facing cloud services across productization, tenancy, provisioning, metering, billing, service operations, and lifecycle using a practical 12-point checklist.
- GPU Cloud Profitability: Why Utilization Alone Is Not EnoughLearn why technical GPU utilization is different from billable time, and how saleable capacity, realized pricing, fixed and variable costs, and break-even interact in a hypothetical 32-GPU model.
- Building a GPU Cloud: Open Source vs. Integrated Operations PlatformsCompare self-built open-source GPU cloud stacks with integrated operations platforms across orchestration, tenancy, metering, billing, failure recovery, extensibility, support, and multi-year TCO.
- What Is On-Demand GPU Service?Understand on-demand GPU as a consumption model rather than a single virtualization or pricing method, and see how capacity, provisioning, metering and release work together.
- What Is a Cloud Service Catalog?Learn how a cloud service catalog turns infrastructure capacity into orderable products and connects product definitions to policy, provisioning and commercial operations.
- From GPU Hosting to GPU CloudLearn how data center operators can evolve GPU hosting into a customer-facing cloud service by adding productization, self-service, automated provisioning, tenancy, metering and lifecycle operations.