The Day AI Made the Headcount Roster
The first numbers in this morning’s news are laid out like a curious set of books. In its “2026 Industry AX Customer Case Collection,” Bespin Global disclosed that it analyzed 33,924 of its company-wide monthly tasks, selected more than 900 automation candidates, designed and validated 751 agents, and is now running 511 of them company-wide on a continuous basis. The results: 36,800 hours saved per year and a 99% reduction in human error. Read as just a press release, the story is nothing new. But the scene that has taken shape, and is worth reading in this morning’s news, is that a vendor now offers its own continuous-operation numbers to customers as “evidence,” and customers accept them as a benchmark. The enterprise AI market has entered the era where “how many agents you run” has become the language of pride.
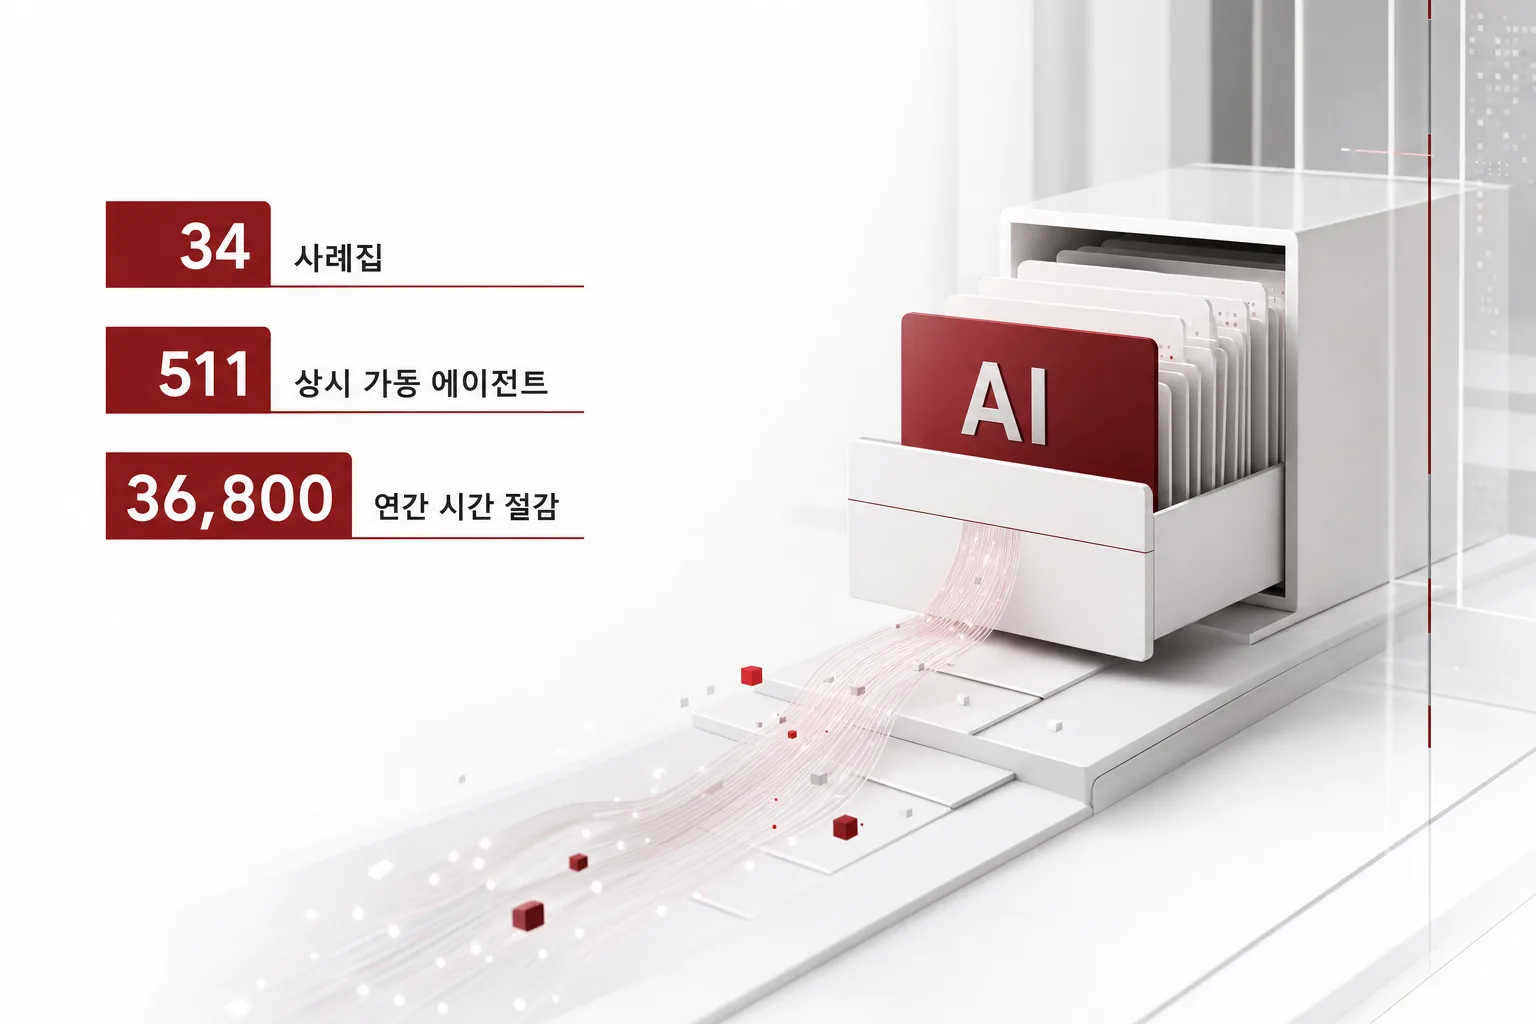 Illustrating the core concept of the article.
From Pilot Success to Operating Numbers
Let’s look back at the language of pride used in this space over the past few years. A couple of years ago, “we did a pilot” was the end of the brag. Last year, “our model is good” worked. This year it is “N agents running continuously, X hours saved, Y% fewer errors.” The bar itself has moved. Today’s in-depth reporting summarizes it like this: the evaluation axis of the enterprise agent market has shifted from pilot success to the scale of continuous operation, hours saved, and error-reduction figures, and competition in the domestic MSP industry has moved from model capability to the scale and performance of agent operations.
The industry map released this morning is itself a cross-section of this era. IT Chosun’s “Agentic AI Map 2026” reports that the outline of the representative ecosystems in the domestic agent market is not yet clear, so the Korea Intelligent Information Society Promotion Institute (NIPA) has begun industry mapping, and within the same mapping it reports that Naver Cloud disclosed a full-stack strategy connecting its own models through to infrastructure. In a market still drawing the map, a company has appeared that published its own books first.
The case collection follows the logic of this era. Of the 34 cases in total, 14 are domestic real-world projects, including KB Life, Woori Financial Group, Korea Hydro and Nuclear Power, and the Korea Forest Service. The global figures the collection cites stand out too: banks disclosing AI return on investment rose from 4 to 15 in a year, and manufacturing reported a 40% productivity gain and a 48% reduction in lead time. Bespin Global calls this approach Self-Proof. It is the principle of proposing only solutions it has first applied and validated on its own work. From the standpoint of a customer calculating the risk of adoption, the logic is simple: if the vendor cannot run about 500 in its own company, why should it be able to run them on our data? Performance figures have become the trust mechanism.
There is one point of contention attached to the numbers: whether the result of running 511 inside a single company reproduces as-is on the ground at an individual customer. Today’s reporting pinpoints this as the core question of the case collection. The ability to reproduce will likely determine the trust behind future bid competition. If the numbers appear only in the vendor’s books, they are still a press release; if they stand just as well on the customer’s ground, they become a standard, since creating that difference is the work of the operations layer.
The 240 Between 751 and 511
Among the listed numbers, there is one place worth pausing. The designed and validated agents number 751, but the continuously running ones number 511. The gap of 240 is a phenomenon that only becomes visible when you treat agents as headcount rather than projects. It means that among the agents you hired, some never make the payroll. Some are validated but not deployed, some go unused, some underperform against expectations. This gap foreshadows the next battleground.
So the brag of the operating-numbers era cannot rest on the single number 511. When a customer asks “what happened to the other 240,” the answer is itself the platform’s operation record: which agents were stopped, why, and who decided. If you cannot answer that question, the number is not an asset, it remains only a brag.
When headcount comes, management follows. When a pilot runs a few dozen, one or two owners and common sense are enough. At 511 running continuously company-wide, you have to answer different questions: what permissions did you give which agent, what data did it touch, who approved it, and who takes responsibility when it makes a mistake. Today’s reporting reads it this way: once the reference point of 511 running is confirmed, agent-operations governance spanning audit, approval, monitoring, and performance measurement becomes a mandatory item in procurement for financial, public, and manufacturing adoption. The number shows “the scale you run.” The system that supports the number shows “the order you run.” The next bid is decided on the latter question.
The Other Side Is Already Moving
The signals do not come from Bespin Global alone. Data Som’s analysis this morning says that chaebol heads are stepping up to AI directly. LG held business-reporting meetings across all of its subsidiaries for a month, putting an AI-centered future growth strategy as a core agenda item, and it has set a target to expand an 80MW AI factory in Chungcheongnam-do by the first half of 2028. Since its “AI Transformation” declaration in June, Samsung has also moved into president-level bootcamps, intensive executive training, and AI-dedicated units at each affiliate, and its DX division has allowed the concurrent use of multiple external AI services, including ChatGPT, Gemini, and Claude, in its work. When the decision-making table rises to the chaebol heads and multiple models are used together within the same organization, the scarce resource is no longer “which model” but “the layer that holds orchestration and governance on top of the models.”
The agenda of public investment points the same direction. Deep Brains AI was selected as the sole executing institution for a 1.5 billion-won R&D project from the Ministry of SMEs and Startups. The project develops an AI video agent that produces and edits video through conversation, and the research subject itself is error detection, automatic recovery, and multi-agent task-division structure. In effect, the reliability standard for enterprise agents is being formalized as a state-funded project, with commercialization targeting 2028. On this side, Naver Cloud launched a free AI security self-check that lets you work through 21 questions across 7 domains without installing a solution or registering company information. One of the check items is whether you manage access permissions to in-house AI systems. The entry ticket to adoption is no longer the demo. It is governance self-inspection.
What Changes When 511 Becomes the Standard
When the number of continuously running agents becomes the industry’s benchmark, the question each company receives changes. It is no longer “can you run 500 agents now” but “can you explain that it is safe, prove it, and scale it to 5,000.” Scale up and three walls come first.
The change reaches the format of bidding. Until now, the buyer’s evaluation items were the model’s benchmark score and the vendor’s track record. Going forward, items like “the vendor’s own number of continuously running agents” and “the existence of an operations audit record” are likely to be written into bid documents. A phase is coming where the shape of the number itself becomes a qualification requirement.
First is permission. You cannot give every agent the same freedom. An agent that reads documents and an agent that executes a transfer must have different grades of autonomy. Second is the record. When it did what must remain as evidence that can be brought out and shown. In financial and public sectors this is a procurement requirement, not a nice-to-have feature. Third is isolation. The cost of one agent’s mistake must not spread across the whole organization; it must be cut off inside a sandbox. Cost is attached here too. The model cost per unit of work is a variable that cannot be ignored, and where you run it is also an operations question. Overseas cloud, your own closed network, or a hybrid that mixes both. As the IT Chosun mapping reported, the fact that even the Bank of Korea has built dedicated AI inside a closed network symbolizes that public and financial procurement is moving from SaaS subscription to dedicated platform construction.
In the operating-numbers era, “can it run anywhere” itself becomes a spec. A notable point is that Bespin Global’s platform runs on the multi-cloud of AWS, Google Cloud, and Naver Cloud. When metrics become standards, the format of proposals unifies too. The shape of “number of running agents, hours saved, error reduction rate” will become the industry’s common metric system, and vendors will prepare their answers in the same format. Today’s reporting reads that demand will concentrate on vendors that provide orchestration, operations, and measurement as a single platform.
Through the Paxis Lens
How would ThakiCloud see this morning’s list? Paxis is ThakiCloud’s agent-native cloud, already a formally released product. It manages Skills and Tools, Policies, and Audit Logs as first-class resources. It is a structure that answers “under what system you run” rather than “how many you run.”
Hold the four pains the news revealed against Paxis, and it is not a forced match. Autonomy: governance from L0 to L3 decides how much freedom each agent gets, and a policy gate stops it when it crosses that line. The audit log is the evidence of “when it did what,” and the isolated sandbox holds the cost of a mistake inside a single task. The MCP connector and skill market remove the need to hand-build the tools an agent calls every time, and on the ground where data must not leave, it keeps working when moved to sovereign or on-premises K8s, ai-platform. CostRouter picks the most fitting model for each task and converts the agent’s token unit price onto operating numbers. Bespin Global’s 511, Samsung’s concurrent use of multiple models, Deep Brains AI’s automatic-recovery standard, the Bank of Korea’s dedicated closed-network build. Each is a problem that needs this layer, and Paxis sits in the position of taking them all on a single platform.
Naver Cloud is drawing the map of its own model full-stack, and hyperscalers are competing over the execution layer. In that board, the position Paxis takes is to run the core of agent operations on any cloud, the narrative of One Paxis. Any Cloud. The side that makes the same numbers reproducible in more fields, on more clouds, will take the advantage of the operating-numbers era.
The numbers listed this morning are, in the end, not a story about headcount. They are a story that the market has started to demand payroll-register-level evidence. The era when a successful pilot alone was a brag is over. From here the question will go to “how many you run, and under what system you run them.” This morning’s 511 is not the destination of this story, it is the starting line. The numbers of the companies that follow will be published aiming at this benchmark, and next season’s books will be written on this standard. The one that answers that question first will take the next 511 bids.
References
This article was written by synthesizing the news below.
- Digital Times, UK’s Enscale, pushing for listing, in talks over $45 billion computing contract with Anthropic
- IT Chosun, [Agentic AI Map 2026] Naver Cloud, from its own models through to infrastructure…
- Digital Today, [Tech Inside] A second WeWork? The reality behind the “AI bubble” theory from NeoCloud
- Economic Review, Bespin Global, which released an AI transformation case collection, discloses results on 34 cases: “Our 511 agents running…
- Women’s Economy, [Card Company Reboot] From consulting to payment… card companies “changing their body” with AI
