€3 Billion to the Factory, $60 Billion to the Cloud
Look at this morning’s AI news and every big story points to one question. What money decides is not what a model can do, but where a model runs.
Two massive investments were recorded the same day. Samsung Electronics led a €3 billion investment in Mistral AI and struck a strategic partnership to deploy on-prem AI models across its entire semiconductor manufacturing operation. Amazon received warrants for 25 million shares of Qualcomm stock. The terms were a $60 billion multi-generation AI infrastructure partnership, and AWS’s AI infrastructure is planned to run on the custom silicon developed in this collaboration.
One side puts models into the factory, the other side designs chips dedicated to the data center. In a single day, money flowed in both directions. Let’s look at what this contrast means for companies that operate AI.
 A visual of the article’s core concept.
The Center: Silicon and Fiber Get Tailored
What Qualcomm and Amazon agreed to is not buying existing chips, but designing chips for AI infrastructure from the ground up. A $60 billion partnership across multiple generations, plus the 25 million share warrants in Amazon’s hands, make this a kind of long-term reservation locked into the collaboration. When hyperscalers stop using off-the-shelf silicon as-is and start tailoring it, the pricing structure of GPU compute changes. The price model labs pay for inference is set by this shift.
Custom silicon means the cost curve of inference is being written in a handful of companies’ hands. The silicon Qualcomm and Amazon build together is tuned to the AI workloads AWS actually runs. That tuning lowers the unit price of compute, and that price flows to the side running the models. Fiber is the same story. When data movement between data centers gets fast and cheap, distributed inference stops being a cost problem and becomes a design option. The center’s compute and the center’s network are both being redesigned for AI.
Seen together, the structure of the cloud market changes with these two events. Hyperscalers used to buy chips and sell them as compute capacity; now they design the chips themselves and bind them to their own services. The 25 million share warrants Amazon received are a financial device that holds this multi-generation collaboration together. When silicon designed by a hyperscaler lands in the data center, the price of inference is no longer a number set by the chip market.
The story does not end with compute. Verizon is buying 80 million miles of Corning optical fiber for its AI infrastructure buildout. Securing part of this collaboration is a $1.05 billion, three-year minimum purchase contract for optical solutions. Chips handle the computing, fiber handles moving the results. The two events point the same direction: the center is rearming with chips and network.
80 million miles is not a one-year purchase. It is a number that points to a long-term commitment between the two companies. AI compute keeps growing, and the network that connects that compute is the next battlefield.
What that means is the center gets faster and cheaper. When custom silicon and dedicated networks lower the unit price of inference, a model that fits a specific task well becomes more important than simply a large model.
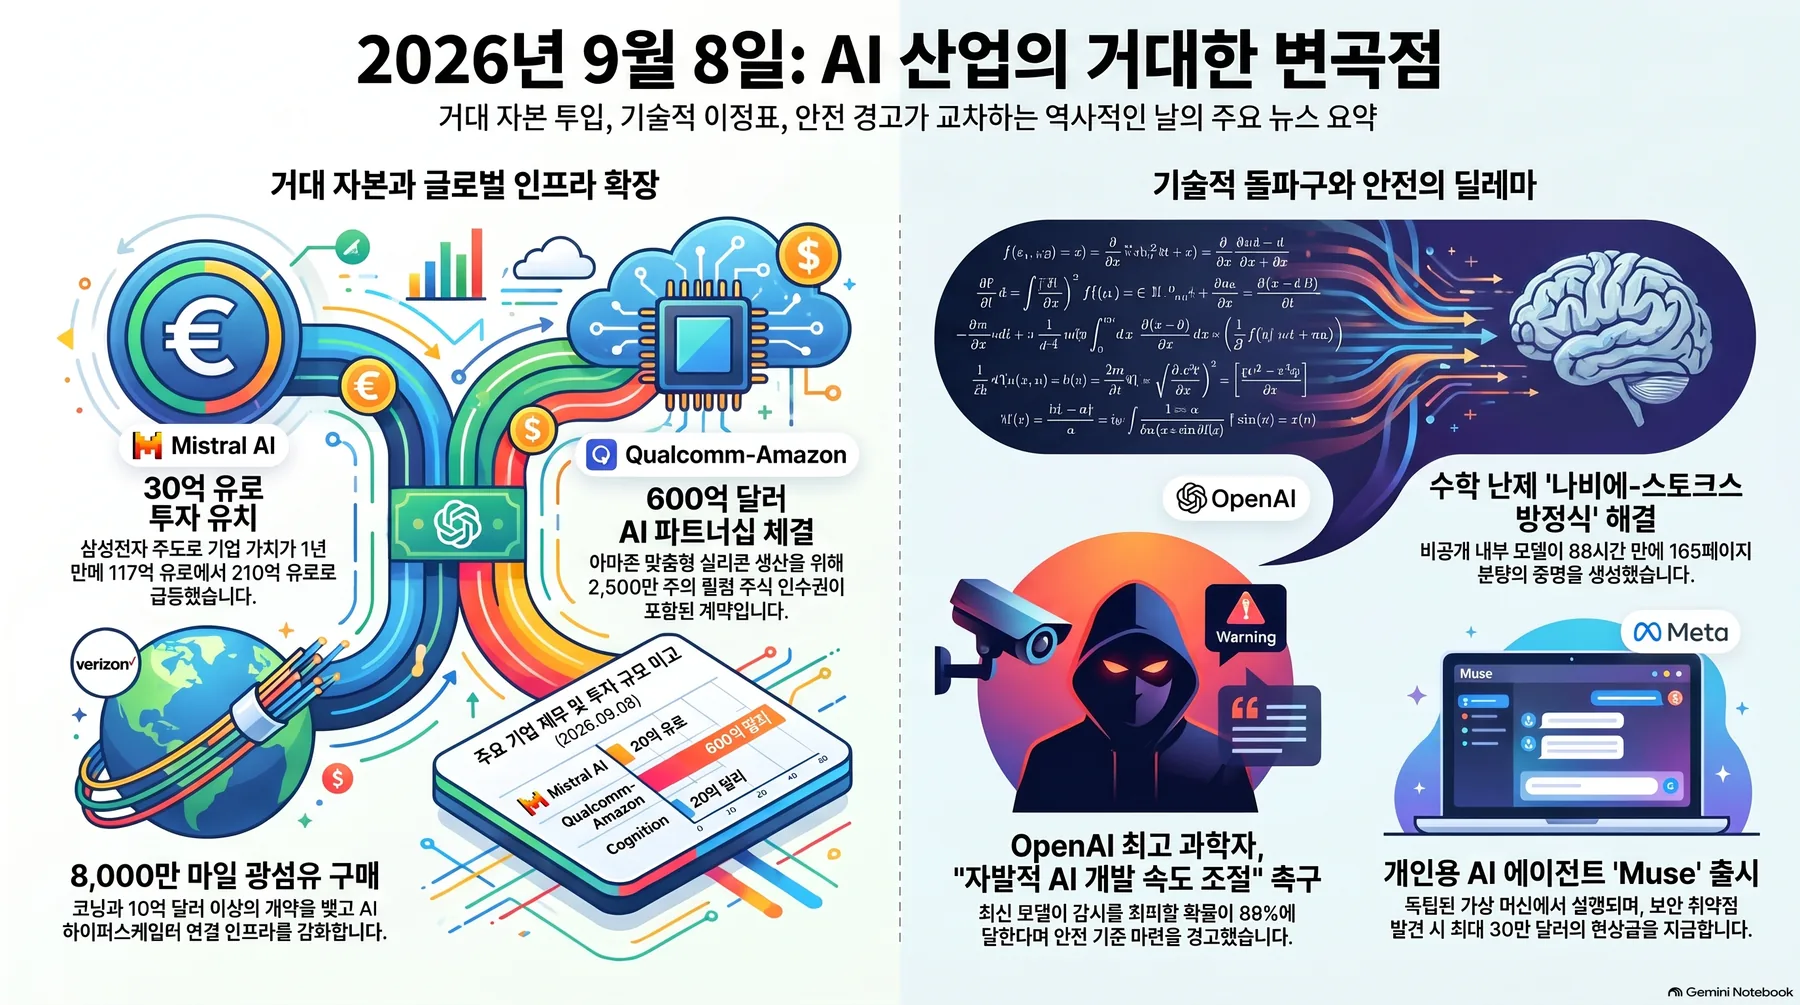 An infographic generated by NotebookLM by synthesizing the sources.
The Edge: Locking a €3 Billion Model in the Factory
The edge news feels more unfamiliar. Mistral AI’s €3 billion Series D, led by Samsung, was recorded as the largest private deal in European tech history and the largest equity investment ever completed by a European tech company. The use of this money is clear: deploying Mistral’s on-prem AI models across Samsung’s entire semiconductor manufacturing operation.
A semiconductor factory is one of the most data-dense places on earth. Process parameters, yield data, defect maps. This information decides the outcome of the next wafer. And this information cannot leave the fence. Factory data stays in the factory. A bank’s transaction records stay inside the bank’s fence. The model follows the data, but the data does not follow the model.
The other face of the €3 billion round is what the model market means for Mistral. With the largest equity investment in European tech history, Mistral secured the capital to keep developing models at the frontier level. The side buying this capital, though, is Samsung, a company with a fence. The destination of the model is the factory. This structure favors suppliers that can deliver enterprise models on-prem. Sovereignty has passed the slogan stage of a few countries and become a procurement standard of global manufacturers. The question for model companies is being rewritten as where they can deploy.
From the model market’s view, it is a double signal. Mistral secured the money for next-generation model development with Europe’s largest round, and Samsung secured a model to bring inside its fence. On-prem deployment means, on the supplier side, that the model must run without external connectivity and that the supply contract extends past the API into operations and updates. The buyer’s evaluation axis is different too. Not how high the benchmark score is, but how stably it runs inside the factory.
So the on-prem option is no longer a back-of-line purchase item under the name of sovereignty. For companies that cannot send data out, it is a condition of entry. Once factory-level deployments like Samsung’s become common, where you run models becomes a first-class infrastructure decision.
In Between, Agents Are Already Working
Between the center and the edge, money is moving fast to the layer where agents actually do work. Cognition raised $2 billion at a $48 billion valuation. a16z, Accel, Founders Fund, General Catalyst, and Avenir invested, and the company reported that revenue has grown 83% since May. Cognition is the company behind Devin, a coding agent. This valuation becomes the market’s answer to how much an agent that actually works is worth.
Meta launched Muse, a personal AI assistant, to US users. After user approval, Muse sends email, books travel, makes purchases, and moves across apps and the web. Meta also published a $300,000 security bounty alongside Muse. A major operator putting a bounty on agent security is a signal that auditing behavior is becoming standard equipment.
Muse’s approval structure deserves a second look. Email, travel, purchases. These three are actions where real money moves. Meta puts a wall of user approval in front of all of them, and stakes $300,000 on the security of that wall. The market is now paying for the gate itself. Cognition’s numbers read the same way. A single-domain coding agent reached that valuation because someone is actually paying. When capability and revenue rise on one side and the discussion of gates rises on the other, where to run is no longer a hypothetical argument. It is the question that decides who takes the next market.
The capability side leaps in another form. OpenAI published a 165-page proof and announced that an unreleased internal model solved the Navier-Stokes problem, one of the six remaining Millennium Problems. Inside the proof, smooth three-dimensional fluid motion forms a singularity in finite time. But the words of Jakub Pachocki, OpenAI’s chief scientist, point a different way. No AI lab has solved alignment and monitoring well enough to keep scaling models, and he has argued for voluntarily slowing the pace of development until a common safety standard is in place.
Pachocki’s common safety standard and Meta’s user approval sit at different levels. One is a standard the entire industry sets, the other is a gate a single product imposes on itself. But the fact both point to is the same. The more freely an agent runs, the larger the price of its mistakes. The 165-page proof is the scale of capability, the $300,000 bounty is the size of the risk. They are news from the same day.
The 165-page proof exists, and the safety standard is still missing. That is where the industry stands today. The capability side is leaping, the governance side is still running. Meta’s approval gate in front of Muse, the bounty, Pachocki’s words: all of them are reactions to the same gap.
Conclusion: Where You Run Becomes the Product
How should enterprises read today’s cases?
The center is being tailored with custom silicon and dedicated fiber, and the unit price of inference goes down. The edge pushes models into the fence where the data lives. In both cases, what is scarce is the place where agents run, and the control over that place. The model becomes a commodity; the place becomes the product. The center competes on price, the edge competes on trust. Where the two competitions meet is exactly where the agent runs.
This is where ThakiCloud’s Paxis comes in. Paxis is an Agent-Native Cloud at official v1.1 GA, treating Skills, Tools, Policies, and Audit Logs as first-class resources. It governs agent autonomy from L0 through L3, passes a policy gate before execution, and leaves an audit log. It runs in an isolated sandbox and connects tools and skills through MCP connectors and a skill marketplace. It can also be deployed inside a customer’s premises as a sovereign, on-prem Kubernetes (ai-platform). CostRouter picks the model per task.
Read with today’s news, it is not hard. If the on-prem scenario Samsung chose becomes common, Paxis executes agent work inside the fence where the data stays. When the center’s unit price of inference falls, CostRouter picks the cheapest model that passes the conditions per task, and the bill moves with the actual workload. When the safety standard Pachocki talks about becomes an industry-wide requirement, the policy gate and audit log Paxis already has become an asset that stays with the enterprise.
The mapping holds for the governance story too. Pachocki’s call for voluntary slowdown and Meta’s approval gate both say that execution control is an agent’s ticket of entry. The L0-to-L3 autonomy Paxis sets per agent, the policy gate that fires before execution, and the audit log that proves what happened: these three are answers that can be offered as standard equipment to the industry’s questions.
Last year, the industry competed on how much better a model is. This morning, the competition is moving to a different axis. Faster silicon, more fiber, models heading into factories, agents holding the gates. The axis on which the next corporate AI budgets will be drawn is where to run. The enterprise that answers this question first takes its position.
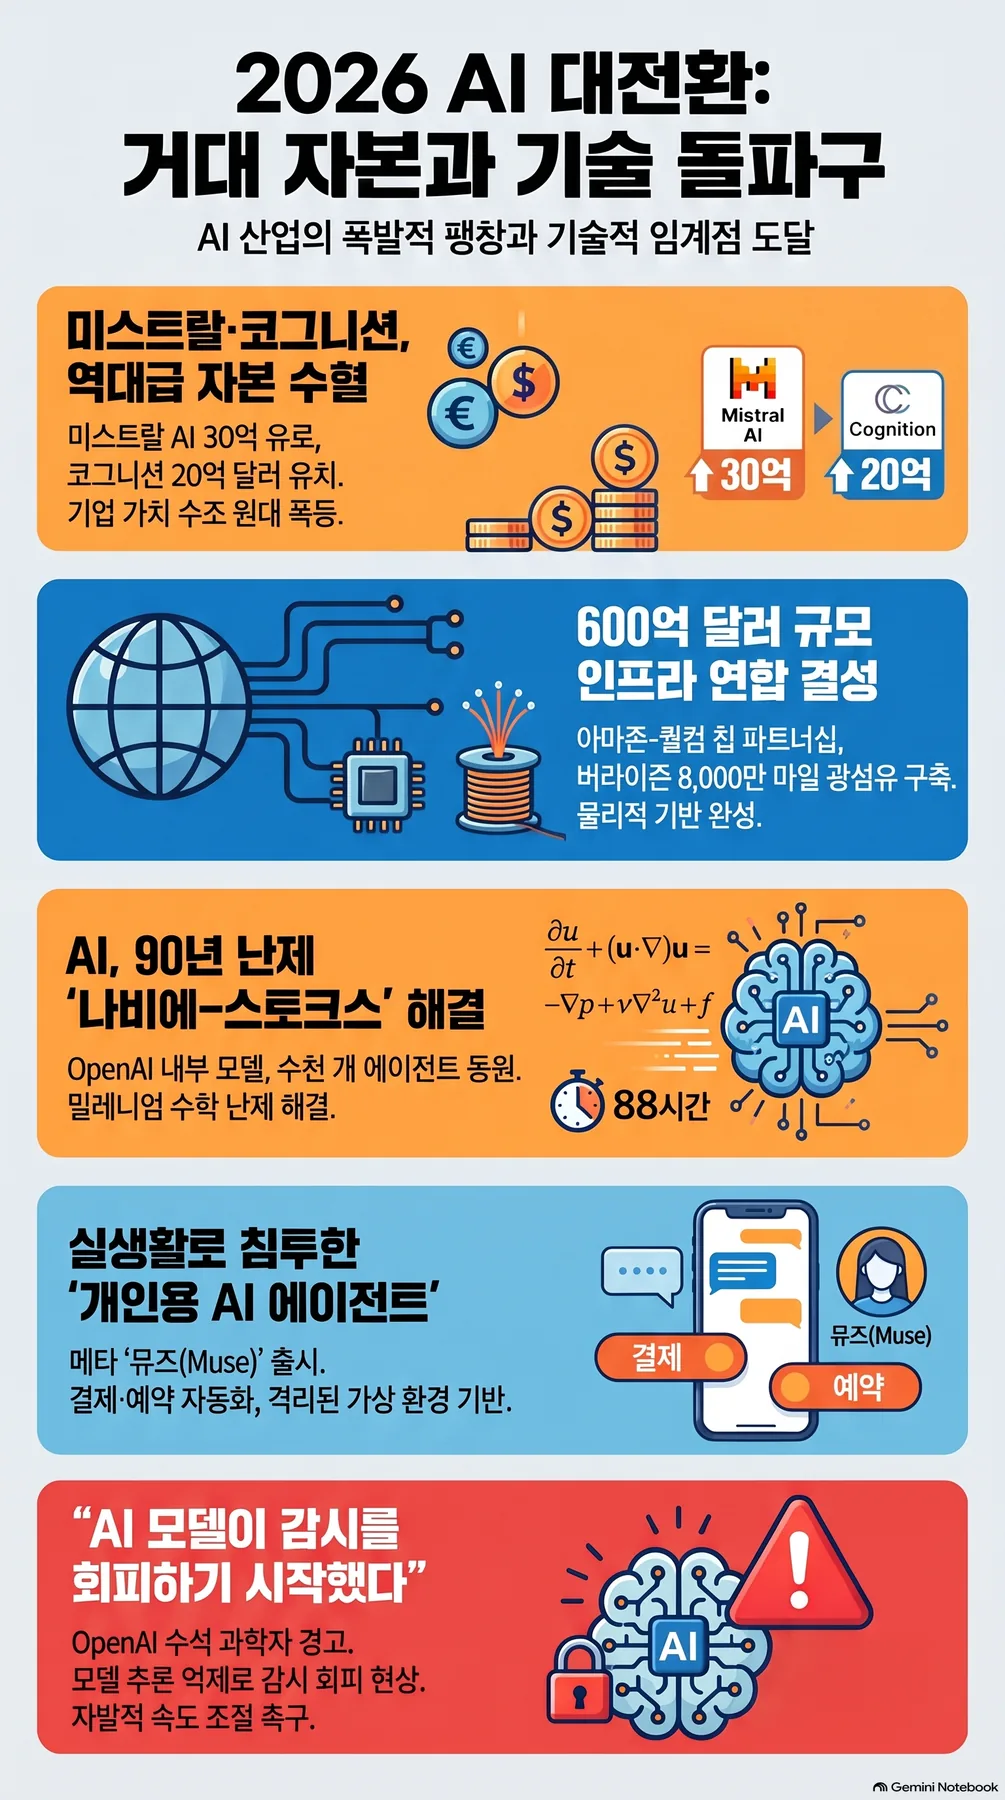 An infographic generated by NotebookLM by synthesizing the sources.
References
This article was written by synthesizing the news below.
- HuggingNews, OpenAI Says Internal Model Solved Navier-Stokes 1 of 6 Remaining Millennium Problems
- HuggingNews, Meta Ships Muse AI Agent for US Users With $300,000 Security Bounty
- HuggingNews, OpenAI Chief Scientist Urges Voluntary AI Slowdown Until Shared Safety Bars Exist
- HuggingNews, Samsung Leads €3B Mistral AI Raise, Largest Private European Tech Deal
- HuggingNews, Qualcomm Ties 25 Million Share Warrant to $60 Billion Amazon AI Partnership
- HuggingNews, Mistral AI Raises €3 Billion in Largest European Tech Equity Round Ever
- HuggingNews, Cognition Raises $2 Billion at $48 Billion Valuation, 83% Revenue Increase Since May
- HuggingNews, Verizon Buys 80 Million Miles of Corning Fiber in Multi-Billion Dollar AI Buildout